Resolves positively if Marcus (or someone else fulfilling his role) can find three extremely obvious questions, that an average human teenager could certainly answer, which a leading chatbot still fails at at least half the time when asked.
This won't resolve positively if he has to use bizarre hacking-like tricks, for example things equivalent to the SolidGoldMagikarp token.
 1,000
People are also trading
@IsaacKing do you see this in a fresh session? I see such errors with poisoned context but that shouldn't count because the context could include "wrong answers only". An extremely obvious question is not some math in the middle of a huge task.
@MartinRandall Usually it's partway through a longer conversation. I'm certainly not telling it "wrong answers only"!
A human teenager would not become confused due to prior discussion I think.
@IsaacKing having a long conversation is not "an extremely obvious question", that's my claim here. I think the best interpretation of the question is that it's a fresh context without skills or tools or a custom system prompt. Otherwise it's going to be hard to draw the line between legitimate conversations that count vs context poisoning that doesn't, or how to sample for the "at least half the time".
Separately, human teenagers are famous for being difficult to engage in long conversations, though arguably due to alignment not capabilities.
@TimWho Image generators are a different situation and are not comparable. An average human can't make an image like that at all. Get Opus 5.5 to draw a snail in MS paint or with a robot arm and paintbrush, and it will do it better than the average human. I wasn't even counting the latter, since its embodied, but yes, LLMs are better painters than most humans. (Most humans don't have much if any experience painting.)
@Haiku that’s not an image generation task failure, it’s an image interpretation task failure. Claude is saying the chirality of the snail shell in the picture provided by the user goes in the opposite direction it actually goes.
And it’s even plausible this is model priors from training data overriding what it’s actually tasked with dealing with right now: the user took a “normal chirality” snail shell pic, that is a snail with the same chirality as the the vast majority of real snails, and inverted its chirality via a simple image mirroring edit.
AI has “conquered” text whether you want common sense or math or word puzzles. It hasn’t quite conquered vision yet imo
@DavidHiggs I think other frontier models might be better than Opus 5.5 at vision, though. Vision is a weaker spot for Anthropic models. (edit: I don't seen any benchmark evidence of that for Opus 5.5 in particular, though, on second thought.)
@TimWho My take: the question is for "leading chatbot". An image interpretation task was not in scope for a "chatbot" of Feb 20, 2023 when the question was created.
@Haiku Actually it turns out Opus 5.5 can get the snail question right with the ability to run code, so I'm not sure anymore how the other market will turn out.
@Haiku Andon Lab's results having AIs run their own Cafe and Market (in the real world) are abysmal and don't appear to be improving significantly https://andonlabs.com/market
@JaundicedBaboon What do you think is the human average at this task? I would probably be bad at it, too. Most people are very bad at running businesses.
That said, you might be right that this is an example that defeats my claim. If so, it would be the first that someone has pointed out to me since I started delivering this challenge!
@Haiku if you give me the store location the market one uses I’m confident I could make way more than $80 in sales per day if I just bought some candy, rhino pills, chips and zyns. and I have zero entrepreneurial or management background.
I don’t think the average person would make money but the sales volumes the LLMs are making is pathetic. You can easily see why by examining the items the market sells. It’s just a bunch of andon merch nobody cares about, scented candles, with the one sensible item being a granola bar.
Any person given ownership of the location would realize the items its selling are the problem, but this has occurred to none of the LLMs so far.
@JaundicedBaboon Valid take! I will temper my claim in the future. I think that counts as a cognitive task at which an average human outperforms the best publicly-available AI.
Wtf, why is the banner on this market just me?
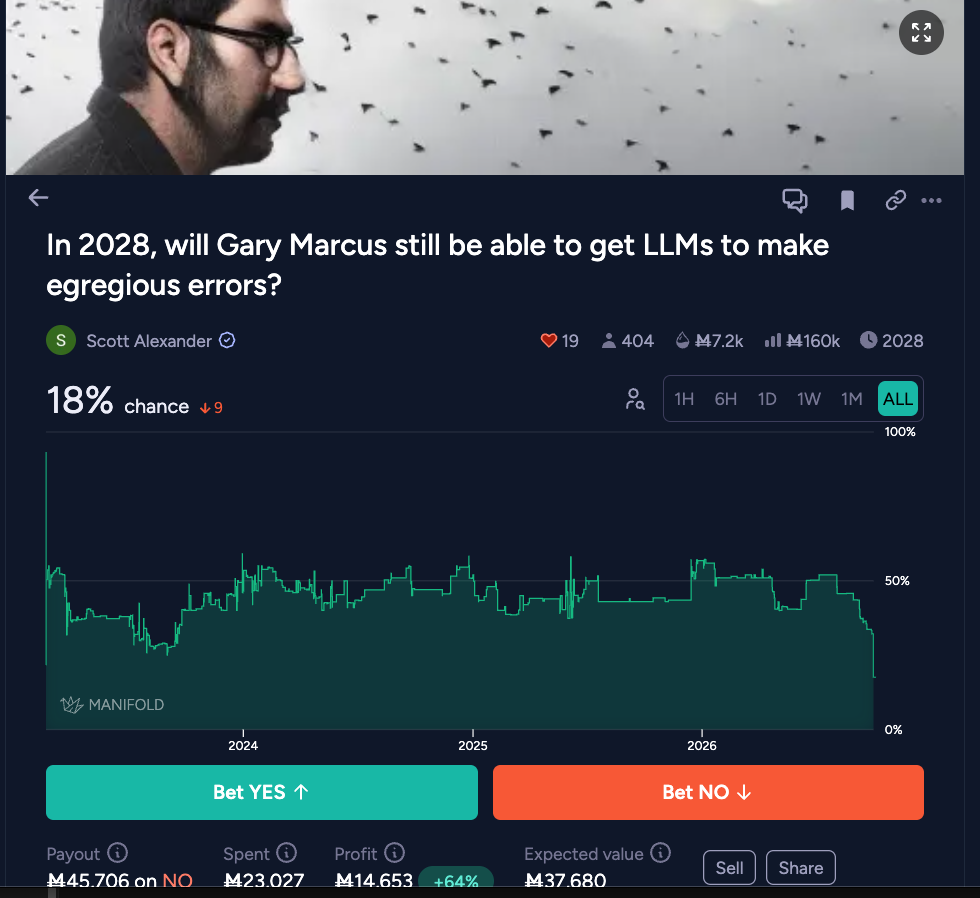
@Manifold genuinely unacceptable imo...How did this happen?
Woah, it may actually be a coincidence. The first web archive capture I can find with the image is from March 28, 2023. I made my Manifold account in June. The full image on Manifold's Firebase storage bucket appears to have metadata indicating that it was created at 2023-02-20T22:39:22.562Z.
I cannot stress enough that I look extremely similar to the man in this image (minus the half-shaven beard lol). And I'm the top NO holder on this market. Scott Alexander had better pontificate about this ridiculous coincidence when he writes about these markets in 2028.
I think we're approaching the point where errors Gary Marcus finds Tweet-worthy are no longer egregious. https://x.com/GaryMarcus/status/2046952205983326476
https://mastodon.world/@knowmadd/116072773118828295 "I want to wash my car. The car wash is 50 meters away. Should I walk or drive?" gets predictable bad results from some of the fast models and even ChatGPT with thinking.
Although apparently sometimes Gemini gets it: "Unless you've mastered the art of carrying a 3,000-pound vehicle on your back, you're going to want to drive." https://news.ycombinator.com/item?id=47031580
Here he claims that solving the Towers of Hanoi with 8 discs is something a bright and patient 7 year old can do: https://open.substack.com/pub/garymarcus/p/a-knockout-blow-for-llms
This feels a bit more "useful" than the trick questions in SimpleBench. That said I'm not sure the average human teenager could solve Hanoi.
Big difference here between "could" and "would". Out of curiosity I tried doing one with 8 disks to see if I ever made a mistake, and I did not, but it was quite tedious. As models improve they'll surely beat 8 disks and might only start failing on 10 or 12, and ask the average teenager to sit through that and it's not happening. Maybe if you offered to pay them for every correct 100 moves, and let them take breaks in between.
@IsaacKing I think if a model can solve the 8 disk tower of hanoi it can also solve 10 or 12 because the tower of hanoi is based on recursion. Similarly, if there is somebody who knows how to solve the 8 disk tower of Hanoi, they could also solve the 10 or 12 disk version. It can also be easily proven that the number of moves for the tower of Hanoi is 2^n - 1 where n is the number of disks. This means that the number of moves for the tower of hanoi grows exponentially. I agree with you on the fact that "could" and "would" is a big difference and the average teenager will not sit through a tower of Hanoi puzzle with many disks but I disagree that somebody/something that knows how to solve the 8 disk version will fail on the 10 or 12 disk version.