If a large language models beats a super grandmaster (Classic elo of above 2,700) while playing blind chess by 2028, this market resolves to YES.
I will ignore fun games, at my discretion. (Say a game where Hiraku loses to ChatGPT because he played the Bongcloud)
Some clarification (28th Mar 2023): This market grew fast with a unclear description. My idea is to check whether a general intelligence can play chess, without being created specifically for doing so (like humans aren't chess playing machines). Some previous comments I did.
1- To decide whether a given program is a LLM, I'll rely in the media and the nomenclature the creators give to it. If they choose to call it a LLM or some term that is related, I'll consider. Alternatively, a model that markets itself as a chess engine (or is called as such by the mainstream media) is unlikely to be qualified as a large language model.
2- The model can write as much as it want to reason about the best move. But it can't have external help beyond what is already in the weights of the model. For example, it can't access a chess engine or a chess game database.
I won't bet on this market and I will refund anyone who feels betrayed by this new description and had open bets by 28th Mar 2023. This market will require judgement.
Update 2025-21-01 (PST) (AI summary of creator comment): - LLM identification: A program must be recognized by reputable media outlets (e.g., The Verge) as a Large Language Model (LLM) to qualify for this market.
Self-designation insufficient: Simply labeling a program as an LLM without external media recognition does not qualify it as an LLM for resolution purposes.
Update 2025-06-14 (PST) (AI summary of creator comment): The creator has clarified their definition of "blind chess". The game must be played with the grandmaster and the LLM communicating their respective moves using standard notation.
Update 2025-09-06 (PST) (AI summary of creator comment): - Time control: No constraints. Blitz, rapid, classical, or casual online games all count if other criteria are met.
“Fun game” clause: Still applies, but the bar to exclude a game as "for fun" is high; unusual openings or quick, unpretentious play alone don't make it a "fun" game.
Super grandmaster: The opponent must have the GM title and a classical Elo rating of 2700 or higher.
Update 2025-09-11 (PST) (AI summary of creator comment): - Reasoning models are fair game (subject to all other criteria).
Update 2025-09-13 (PST) (AI summary of creator comment): Sub-agents/parallel self-calls
An LLM may spawn and coordinate multiple parallel instances of itself (same model/weights) to evaluate candidate moves or perform tree search, including recursively. This is considered internal reasoning and is allowed.
Using non-LLM tools or external resources (e.g., chess engines like Stockfish, databases) remains disallowed.
Update 2025-12-20 (PST) (AI summary of creator comment): Coding a chess engine is not allowed: If an LLM codes up a chess engine (e.g., in Python) and uses it to play, this does not count for resolution. The creator is interested in chess-playing ability as an emerging characteristic of the LLM itself, not through reliance on coded external tools.
Update 2026-06-15 (PST) (AI summary of creator comment): Clarification on what counts as a qualifying LLM vs. a disqualified specialist model:
Specialist/fine-tuned models (e.g., GPT-5.4-rosalind, GPT-5.4-cyber style releases explicitly trained for a specific task) do not qualify.
A model where strong chess ability is an emerging capability (not an explicit training target) does qualify, analogous to how Claude Mythos's cyber ability was emergent rather than targeted.
If a lab publicly admits goal-seeking chess performance (e.g., heavy post-training specifically for chess), it will not count.
If a lab secretly trains heavily on chess and the creator lacks clear evidence of this at resolution time, the market resolves YES.
Chess training as a small fraction of normal training (e.g., ~2% of flops for general reasoning gains) is considered fair game.
 1,000
People are also trading
https://youtu.be/PVVA-_wvKks?si=6lJsen3iEYlxzJOM
It almost beat Gotham. He played a bit badly considering his level but still.
@Velaris note that if Gotham was a super gm and had lost that game, then this market, as written, should NOT resolve to yes. We have no way of knowing if the game was blind chess by the definition given in the market, and this was explicitly clarified multiple times.
@MP , can you clarify this? Assume that at some point in 2027 the standard way for an llm to play vs a human GM involves some tool calls to play moves on a board in a ui (like chess.com just puts a wrapper round GPT-7, or something).
By the end of 2027, it is completely clear that llms are better than the best humans at chess, but there is no public evidence of an llm ever beating a super-GM by just exchanging moves in chat ("communicating their respective moves using standard notation."). How would this market resolve?
@JohnFaben Clearly a model beating a GM in a standard game should count for YES, because removing the blindness handicap strictly benefits the human.
@AdamK No. We’ve been over this point multiple times, and OP has always clarified that it has to be blind. I have bet heavily NO in this market explicitly because of that condition.
@JimHays I agree, and that's how I have understood the chat messages so far (and that's why I hold a no position). But this clearly isn't obvious to most people on reading the description.
Like you, I think this is to a large extent a market on "would a super GM ever play a game they might lose against an llm in a way that this market defines as "blind"?"
@JohnFaben The way I see it, there are two options: by market end, either the models are not good enough or they are so good that super GMs will not want to play them blind on camera. Either way, this leads to NO
@Velaris We might have a model capable of beating a super GM by EOY 2028, but no game is played that confirms it in the conditions given. As I read the discussion, this would still resolve NO
relavent quality content
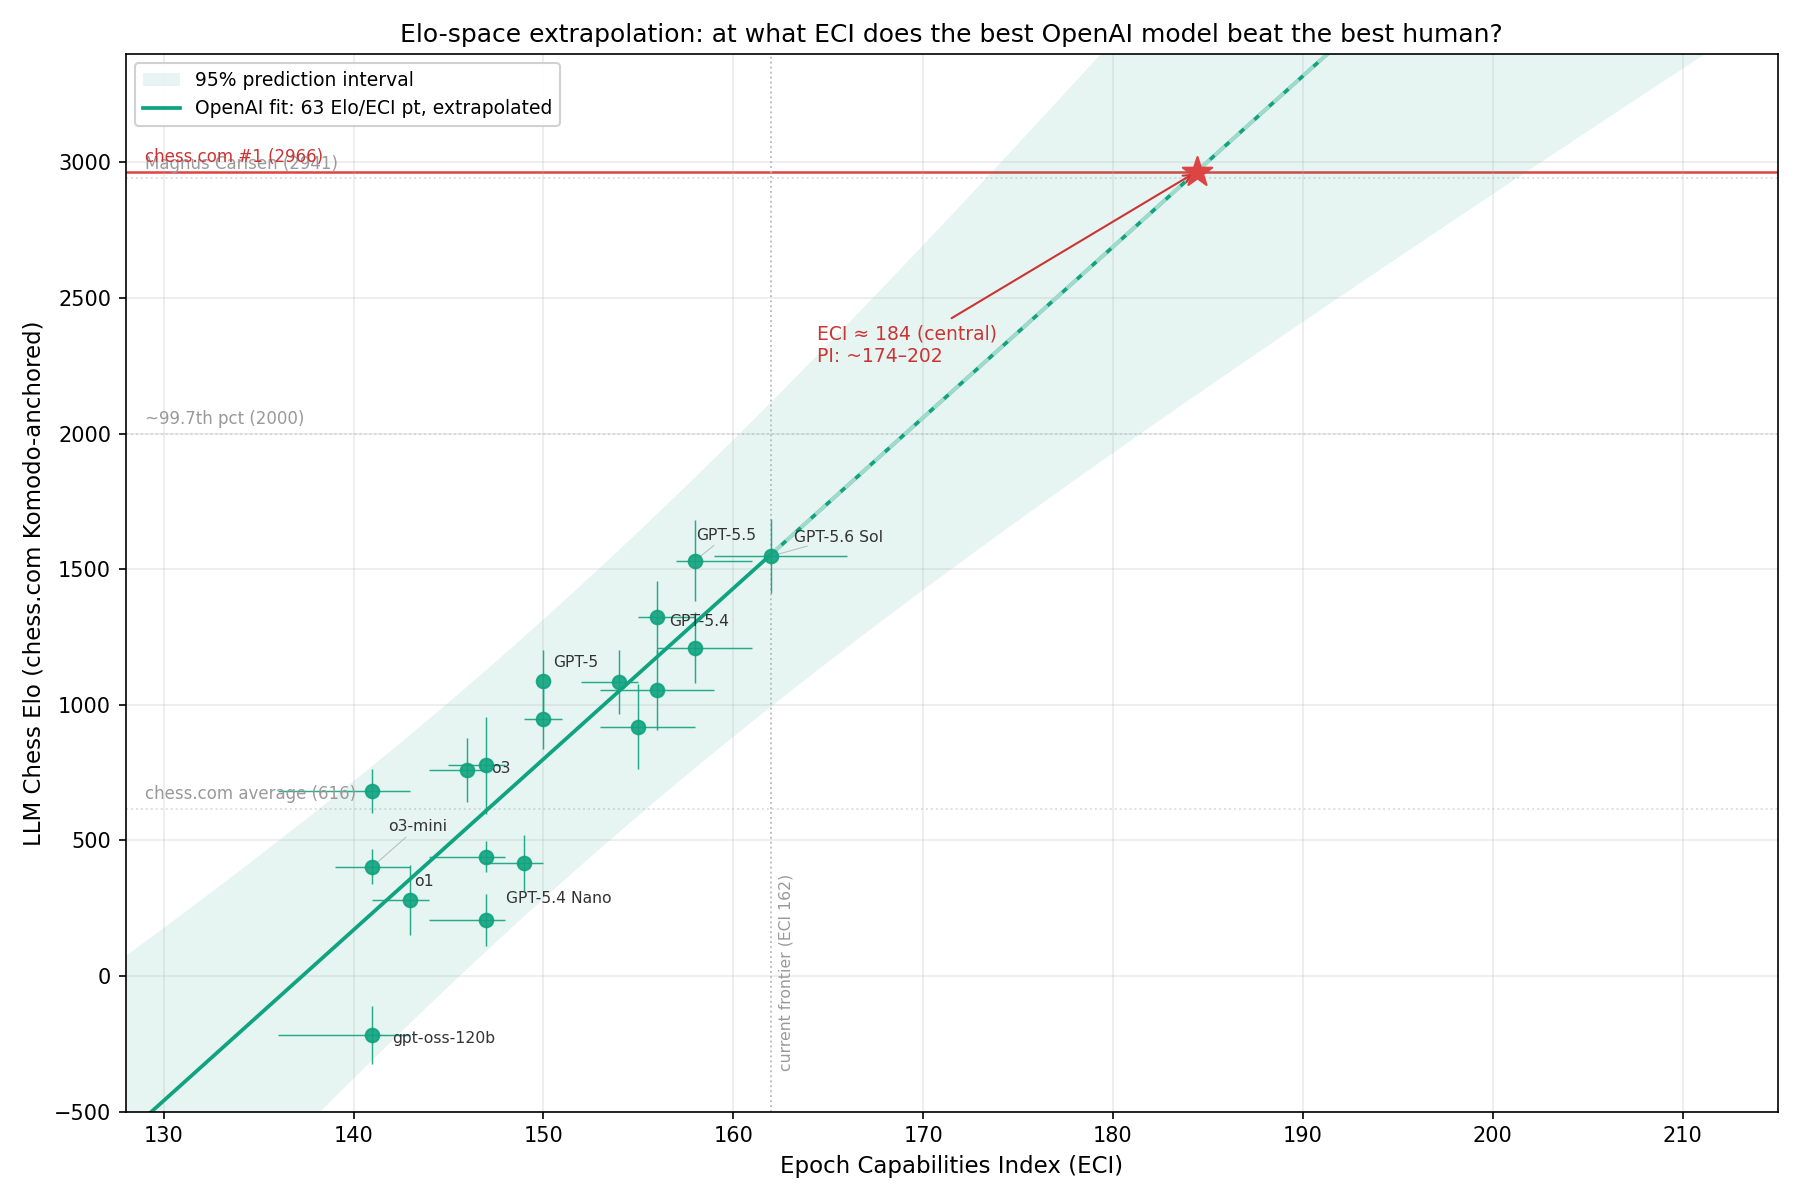
@pietrokc In general, you could run the model yourself and check what tools it calls. Which tool are you concerned of?
@pietrokc I expect if it wanted to use tools, it would call Stockfish which is easily accessible in Python, and the rating would be much higher. But if the actual model rating will be on GM level, it will be hard to use this argument.
@SimoneRomeo Well, I'm concerned about any tools. It has been known since the 90s that computers can beat humans at chess. So this market is only interesting if it's about a specific architecture, namely, pure LLMs. If an LLM is calling code of any kind, that violates the terms of the market. And it's not always clear what Sol, Fable etc did in the background to produce your answer.
@Irigi I don't find that very convincing. It's very easy to imagine an LLM writing a chess script itself which is not as optimized as Stockfish, and running it. That would violate the terms of the market. The entire point of this market is whether an unaided transformer can keep track of the board state and choose good moves. Again, we already know that general computers can.
@SimoneRomeo Yes that is what I'm saying. You said Sol 5.6 is 1500+ Elo right now. I'm asking if it uses code to get that rating. If it does, then your reasoning (gpt 4 -119 --> gpt 5.6 1548) doesn't apply.
@pietrokc for this benchmark sol does the thinking by itself. It has access to tools only for benchmark-provided actions such as get_current_board and get_legal_moves
@SimoneRomeo What benchmark are you referring to? You didn't link a paper or website.
Without those it's hard to be completely sure, but programmatic tools (which get_current_board and get_legal_moves sound like) are NOT allowed for this market:
"Using non-LLM tools or external resources [...] remains disallowed."
Again, the entire point of this market is to see if a pure LLM architecture can keep track of board state across a whole game, and choose good (legal!) moves the whole time. We ALREADY KNOW general computers are better at this than humans.
@SimoneRomeo Here is a properly set up chess harness where models have to do all the work themselves: https://www.kaggle.com/blog/introducing-game-arena
With that setup, Sol 5.6 is 1183 Elo -- below Sol 5.5 at 1305! Not only a far cry from 1548, but not even monotonically increasing.
@pietrokc the benchmark is maxim-saplin.github.io notice it's blind chess, so it's true that LLMs won't be able to recall the board status, but also the grandmaster won't be able to see the chessboard so they will be equally disadvantaged
@pietrokc If you think this market is substantially about whether LLMs will be able to work out board state from a series of moves or legal moves from board state by EOY 2028, I'd be happy to make a market for either or both to take the other side. I think the thrust of this market is whether LLMs can think moves ahead and strategically pick good ones (and whether the game actually happens), with the rote part being essentially inevitable
@Frogswap I agree that picking good moves is most of the challenge but I don't regard keeping track of board state as completely solved, and it increases the chances the LLM will lose. (In some sense this is objectively true since a pure LLM will always sample its response from a distribution so there is always a chance it will output an illegal move, or even something that's not a move at all. But I mean it in a stronger sense than this.)
LLMs with unbounded chain-of-thought are Turing complete, so of course they can in principle keep track of board state and compute legal moves. But I don't think it's clear the ones we have in practice can do it, since their CoT is bounded and they are trained for many tasks besides this one.
@SimoneRomeo That website gives 404
Edit: I think you meant this? https://github.com/maxim-saplin/llm_chess
Edit 2: according to the README.md file, in that setup the LLM can query a "proxy" to get a list of legal moves, and so it doesn't qualify for this market.