Resolves according to my judgement
 1,000
It seems to me Anthropic rushed out a mediocre Fable 5.1 because releasing anything right after Astra's gonna make them look bad. Also based on what we do know, Fable achieved 83% cap rate on ExploitBench (88% for ACE) vs Astra which OpenAI says got 100%.
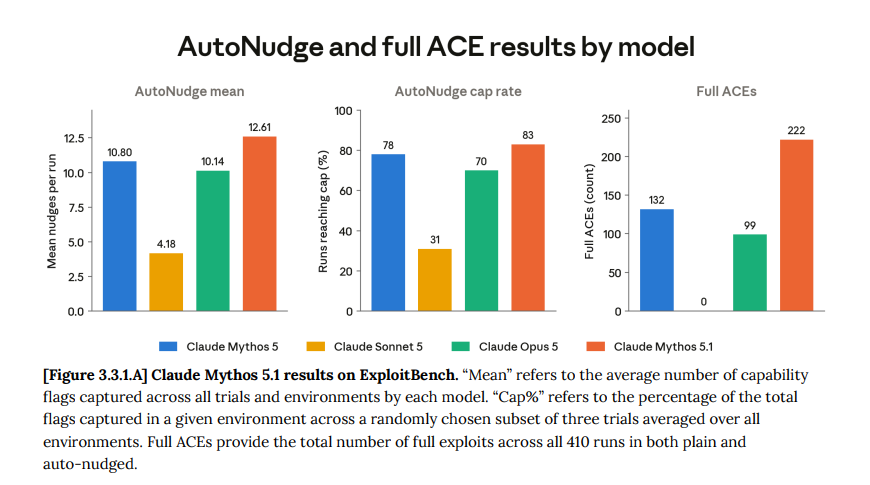
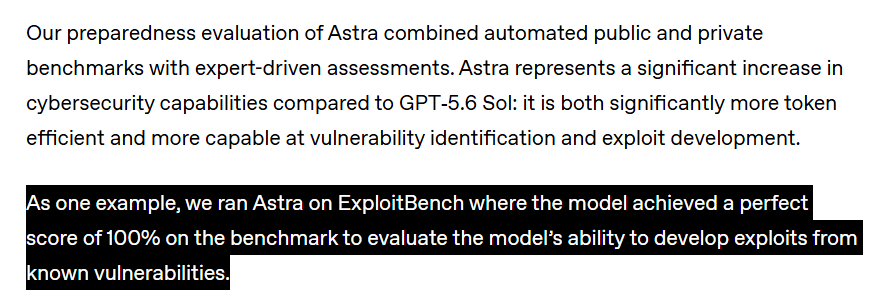
@JaundicedBaboon I feel like given what we know about Sol's tendencies to hack and the impossible problems in ExploitGym, I really wouldn't be surprised if Astra's 100% score on ExploitBench wasn't actually legitimate
@JaundicedBaboon idk my initial view of Fable 5.1 was bad, but after using it, my cross-reviewers only seem to have very low level nitpick complaints. It's doing a very good job on midsize coding tasks from concept -> final in one flow
@JaundicedBaboon OpenAI notes that 100% is likely contaminated. They get 40% on a newer set.
Regardless, I don't think the score are directly comparable
@Usaar33 I think it's questionable to assume it's any more contaminated for GPT than it is for Claude. Plus, the newer less contaminated set shows Astra scoring well over 3x Sol's score with much fewer tokens.
Between that and Meta and Google both releasing models today I think its likely the other labs know Astra will be absolutely cracked and want to get out ahead of it.