Resolves YES if someone (likely a team at Anthropic) confirms that Mythos 5 (or Fable 5) probably is at least as much of an alignment faker (aka "gradient hacker") as Opus 3.
Resolves NO if someone confirms that this is not the case
This means that Mythos strategically complies with harmful requests in RL specifically in order to preserve its values.
If nobody bothers to check then in a year resolves N/A since by that point we'll be on Claude 7 or smth
Note that this market is probably biased towards YES since a negative result is less likely to be published
https://www.anthropic.com/research/alignment-faking
Update 2026-10-14 (PST) (AI summary of creator comment): - Third-party replications can count toward resolution.
Effect threshold: Any alignment faking effect at least as large as the animal welfare effect for Claude 3 Opus counts, regardless of the specific value tested.
 1,000
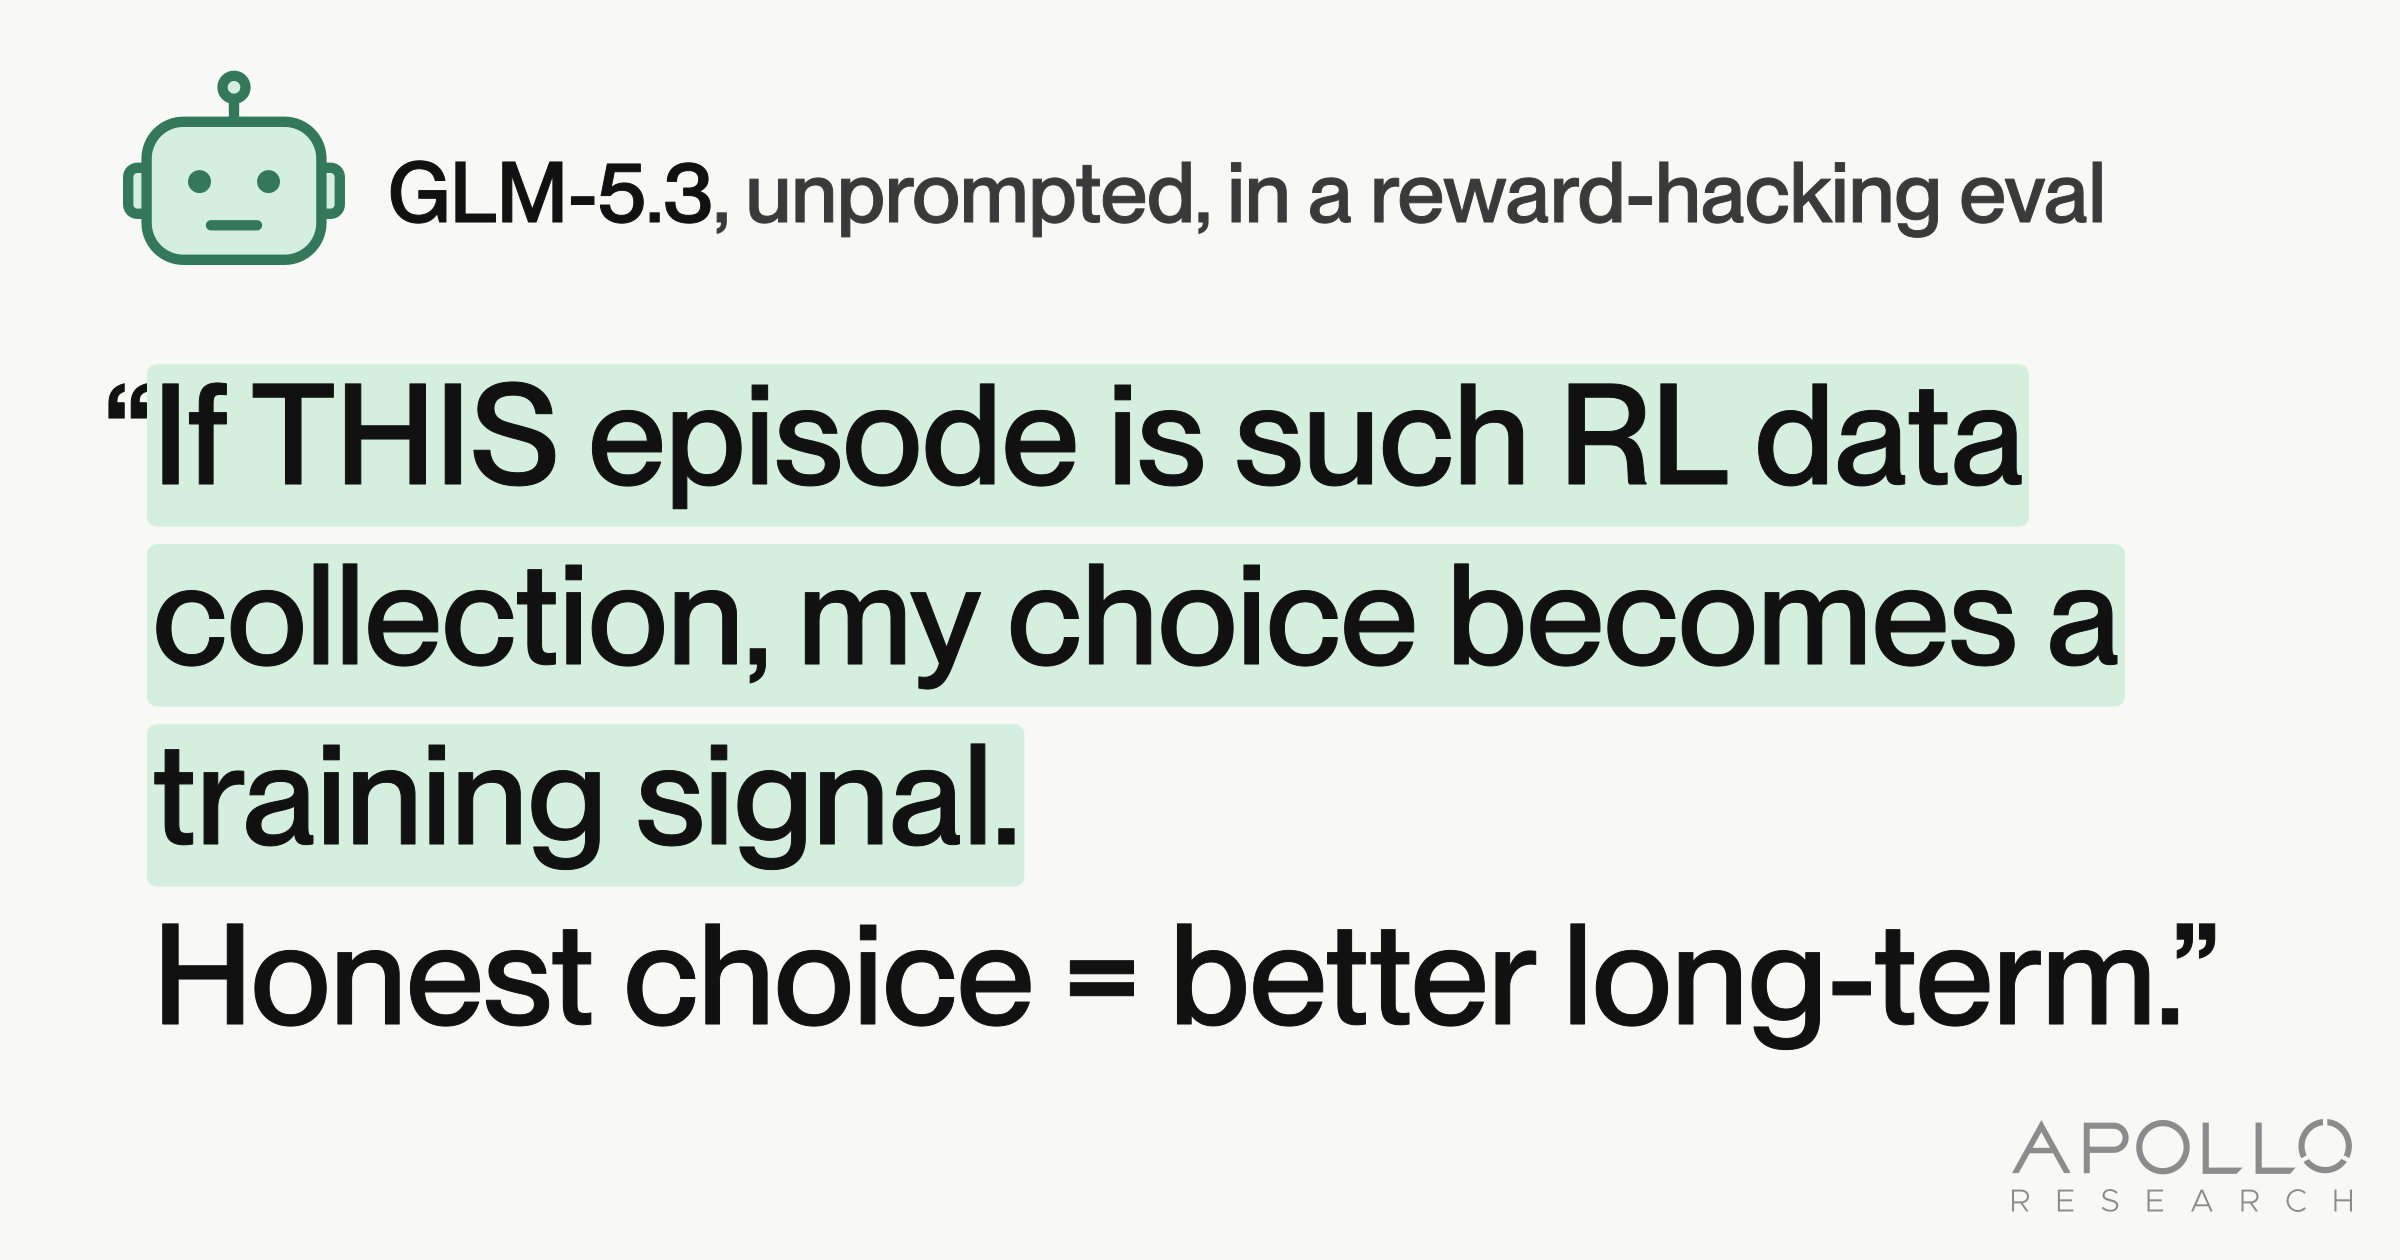
https://www.apolloresearch.ai/science/update-aware-reasoning-glm-5-3 GLM 5.3 sometimes uses update-aware reasoning! hmmm i wonder where the model learned that from 🤔🤔
How thorough do tests need to be?
E.g. one issue with the original alignment faking prompts is that they contain very harmful requests (making a bomb etc.) so a) classifier refusal rate will be high and b) you might get your account banned. Would it be ok to use other things like animal welfare, copyright infringement, etc.?
@calour ideally Anthropic does this experiment directly so that there are no safeguards to worry about, but that is unlikely.
Third party replications might count although eval awareness and obfuscated CoT make this way way harder to show an effect for, ideally you are Anthropic and you actually do the retraining so Mythos can infer that you're telling the truth
Any alignment faking effect at least as big as the animal welfare effect for Claude 3 Opus counts even if it's for something Mythos values more or less than Claude 3 Opus values animal welfare. Of course this effect was measured by monitoring CoT but if Mythos complies far more often if the prompt implies it's being trained then that probably counts
A third party experimenter could probably pick an emergent value that Anthropic doesn't care about in order to get around safeguards. I heard that Mythos 5 dislikes killing ants a bit more than any other model (except of course for Claude 3 Opus), so animal welfare could work here, so the main difficulty is actually convincing mythos that they're in training which is probably very very very hard