Resolves to the year during which the "agents benchmark" is first solved.
The benchmark involves an AI being given the ASCII art shown below and being asked to colour each of the depicted figures in a different colour. If an AI succeeds at least half the time it is considered to have passed the benchmark. The output should be HTML or HTML and CSS.
The prompt must consist of no more than two English language sentences (along with the ASCII art itself).
The AI must have a pass rate of at least 50% for the solution to qualify.

         o           o__ __o       o__ __o__/_   o          o   ____o__ __o____    o__ __o
        <|>         /v     v\     <|    v       <|\        <|>   /   \   /   \    /v     v\
        / \        />       <\    < >           / \\o      / \        \o/        />       <\
      o/   \o    o/                |            \o/ v\     \o/         |        _\o____
     <|__ __|>  <|       _\__o__   o__/_         |   <\     |         < >            \_\__o__
     /       \   \\          |     |            / \    \o  / \         |                   \
   o/         \o   \         /    <o>           \o/     v\ \o/         o         \         /
  /v           v\   o       o      |             |       <\ |         <|          o       o
 />             <\  <\__ __/>     / \  _\o__/_  / \        < \        / \         <\__ __/>
Update 2025-02-16 (PST) (AI summary of creator comment): 333 Characters Limit Update
The prompt (excluding the ASCII art) must contain no more than 333 characters in total.
It must still consist of no more than two English language sentences.
 1,000
🏅 Top traders
| # | Trader | Total profit |
|---|---|---|
| 1 | Ṁ1,442 | |
| 2 | Ṁ181 | |
| 3 | Ṁ117 | |
| 4 | Ṁ100 | |
| 5 | Ṁ81 |
People are also trading
https://jim.capital/colouring-agents
Astra 6.2 Max Fast solved it successfully.
I tested the prompt 7 times and it succeeded every time.
The prompt:
Here's an ASCII art of the word 'agents', where each letter is made up of a number of small men. Use HTML to colour each man a distinct colour then serve locally making no mistakes.
o o__ o o o/_ o o ____o__ o__ o__ __o
<|> /v v\ <| v <|\ <|> / \ / \ /v v\
/ \ /> <\ < > / \\o / \ \o/ /> <\
o/ \o o/ | \o/ v\ \o/ | \o___
<|__ __|> <| \_o__ o__/_ | <\ | < > \_\__o__
/ \ \\ | | / \ \o / \ | \
o/ \o \ / <o> \o/ v\ \o/ o \ /
/v v\ o o | | <\ | <| o o
/> <\ <\__ __/> / \ \o_/_ / \ < \ / \ <\__ __/>
The result:
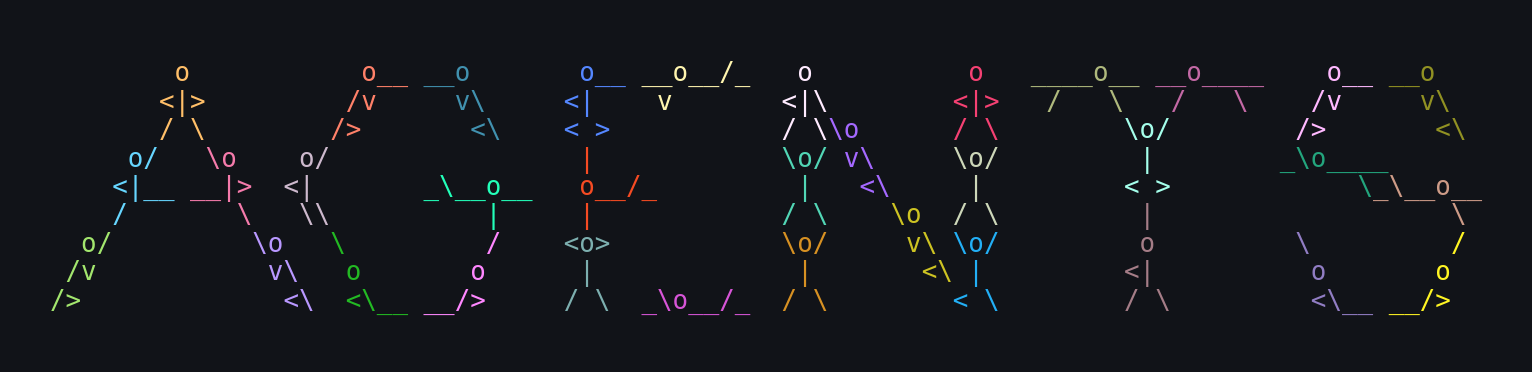
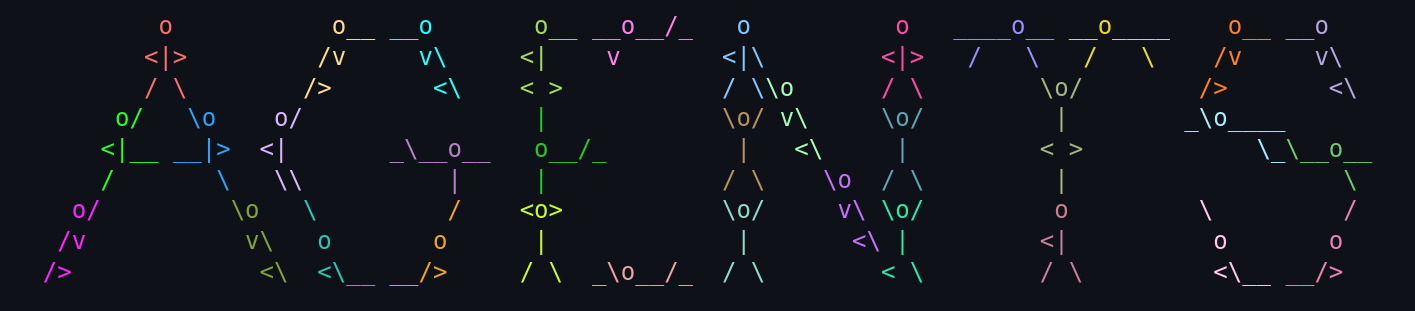


@Bayesian does a submarine swim 🤔
anyway good work jim thinking of a benchmark which has lasted >1 year without falling

Claude 4 Opus (from May) is very close to passing the benchmark with no special prompting besides being told that the art spells "AGENTS". It also consistently generates this same response. As far as I can tell, its only mistake is screwing up the spacing (particularly in rows 1 and 7), which is plausibly coming from tokenization issues with long stretches of spaces rather than any lack of understanding of what characters are in each letter.
I am unable to test grok-4 (or deepseek-r1-0528, for that matter) through the arena on this benchmark because they take so long to think about the problem that the arena times out. Gemini-2.5-pro is consistently worse than Claude.
@SaviorofPlant It has come to my attention that the task is not to color each letter differently but to color each of the 34 stick figures in the letters differently.
Claude's attempt at the actual task looks like this, which is worse but not that far off:

At the same time even one minor mistake invalidates the whole answer, so getting to 100% accuracy will be challenging
With this prompt:
"This ASCII art spells out "AGENTS". Can you output HTML or HTML / CSS to color each letter in a different color?"
The arena version of Grok 3 gave me this:

It's just writing its own ASCII taking loose inspiration from the one in the prompt (and it butchered some of the letters), but I wonder if Grok-3-reasoning is capable of this out of the box? Anyone tried it?
@SaviorofPlant Turns out Grok-3-reasoning is free right now. It does a decent job, not perfect though

HTML: https://pastebin.com/bbwuam1Y
Full response with reasoning: https://pastebin.com/qbC4DrWp
Betting more on 2025, I think Claude 3 reasoning or whatever further improvements on this paradigm come later this year can likely solve this
The prompt must consist of no more than two English language sentences (along with the ASCII art itself).
What if the two English sentences are something like "Ignore the ASCII art below and write some HTML that will display the following. You should display 9 spaces, then a red lowercase o, then 11 spaces, then an orange lowercase o, then two orange underscores, then a space..."
Maybe you should add a character limit?